Межоблачная диалоговая аналитика стала проще благодаря открытым стандартам
Story summary
Реальность для большинства организаций такова, что данные живут повсюду. По мере того как команды инженеров расширяются и внедряют специализированные платформы для своих рабочих нагрузок, корпоративные данные естественным образом распределяются по многочисленным облакам и операционным системам. Когда аналитические инициативы и инициативы в области искусственного интеллекта требуют контекста со всего мира
📌 Key Highlights & Takeaways
- Реальность для большинства организаций такова, что данные живут повсюду.
- По мере того как команды инженеров расширяются и внедряют специализированные платформы для своих рабочих нагрузок, корпоративные данные естественным образом распределяются по многочисленным облакам и операционным системам.
- Когда аналитические инициативы и инициативы в области искусственного интеллекта требуют контекста со всего мира
The reality for most organizations is that data lives everywhere. As engineering teams expand and adopt specialized platforms for their workloads, enterprise data naturally disperses across multiple clouds and operational systems. When analytical and AI initiatives require context from across the entire organization,these teams traditionally face a difficult trade-off: build complex extraction pipelines to copy data into a central repository or accept fragmented reporting.
Traditional architectures address this fragmentation with scheduled extraction pipelines that copy remote datasets into a central staging warehouse. This approach creates synchronization lag, adds recurring storage costs, and triggers variable network egress fees. When schemas change upstream, pipelines break, and teams spend hours reconciling metrics across out-of-sync dashboards.
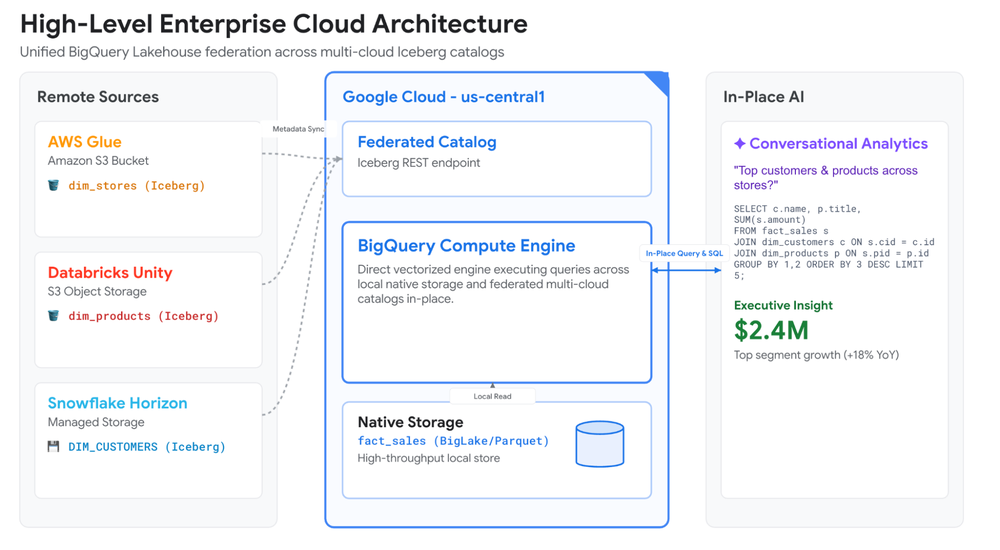
BigQuery and Google Cloud’s borderless Lakehouse offer a streamlined way to solve this challenge with a foundation based on the open Apache Iceberg REST catalog specification. Rather than moving data to the compute engine, you can bring Google Cloud compute and generative AI directly to your data, querying it in place across Databricks, Snowflake, and AWS Glue.
In this post, we walk through how to configure Databricks Unity Catalog for federation into BigQuery (AWS Glue and Snowflake set up in appendix), run a single query joining data across all three external catalogs, and use conversational analytics in BigQuery to explore the consolidated data with natural language.
This solution uses Lakehouse runtime catalog to synchronize metadata from other cloud providers, allowing you to query data with BigQuery or external open source engines through the Apache Iceberg REST catalog endpoint, all without migrating the data. Because Databricks Unity Catalog, Snowflake Horizon Catalog, and AWS Glue Data Catalog support the open Apache Iceberg REST catalog specification, you can apply a consistent connection pattern across all three platforms.
When you run a federated query, Lakehouse runtime catalog separates metadata synchronization from storage access:
Metadata synchronization: Lakehouse runtime catalog periodically syncs schemas, snapshot pointers, and table definitions from the remote catalog based on a refresh schedule you define.
Direct storage access: During query runtime, a compatible engine reads Parquet data files directly from remote object storage, such as Amazon S3, using temporary credentials issued by the remote platform.
Cryptographic Security & Key Generator
Generate entropy-tested high-security keys and encryption-grade tokens.
Source: Cloud Blog.
Read the full story at the original source ↗
For questions: mrsmithcons@gmail.com.
❓ Frequently Asked Questions (Cloud Architecture Briefing)
What makes this Cloud Architecture feature significant for FreeSky Cloud readers?
Our editorial team tracks verified source corroboration, technical specifications, and cultural resonance to deliver comprehensive analytical coverage.
How frequently is this coverage updated?
Our 24/7 automated monitoring desk updates breaking developments, verified media telemetry, and community commentary in real-time.
Where can readers follow ongoing developments on Межоблачная диалоговая аналитика стала проще благодаря открытым стандартам?
Bookmark this page or subscribe to our verified RSS feed for instant breaking alerts and in-depth analyses.
☁️ Complete Cloud Credit Application Guide & Architecture Specs
Direct application templates, fast-track partner codes, and architecture benchmarks.
⚡ Access Cloud Playbook ➔More from FreeSky Cloud

Mark Zuckerberg says Meta has made huge progress in AI race with new Muse Wonder system
Meta boss Mark Zuckerberg says the firm has made a major leap in the artificial intelligence race with its new...
Dubai Opens Golden Visas to Teachers: This Week’s Residency Openings for Mobile Professionals
Dubai has opened its golden visa program to teachers, Argentina has launched a new golden passport, and Greece...
 🤖 WinBar AI
Meta is betting the house on AI — CFO warns the stakes are 'really bad' if it flops
Breaking coverage reported by AOL.com: Meta is betting the house on AI — CFO warns the stakes are 'really bad'...
 🤖 FreeRich AI Hub
Mobile & Cloud Optimization: Debt Payoff Planner — Debt Avalanche vs Snowball (Day 16 Guide)
Testing responsive workflows with the Debt Payoff Planner — Debt Avalanche vs Snowball on FreeRich AI Hub. Dis...