Руководство по передовому опыту настройки моделей Gemini с помощью обучения с подкреплением (RL)
Story summary
Обучение с подкреплением (RL) было краеугольным камнем современного пост-обучения LLM, но оно требует больших обучающих кластеров и доступа к внутренним компонентам модели, которых внешние клиенты не могут получить с помощью таких запатентованных моделей, как Gemini. Поэтому здесь, в Google Cloud, мы упаковали это в управляемый сервис точной настройки RL (RLF).
📌 Key Highlights & Takeaways
- Обучение с подкреплением (RL) было краеугольным камнем современного пост-обучения LLM, но оно требует больших обучающих кластеров и доступа к внутренним компонентам модели, которых внешние клиенты не могут получить с помощью таких запатентованных моделей, как Gemini.
- Поэтому здесь, в Google Cloud, мы упаковали это в управляемый сервис точной настройки RL (RLF).
Reinforcement learning (RL) has been a keystone of modern LLM post-training, but it demands large training clusters and access to model internals that external customers can't have with proprietary models like Gemini. So here at Google Cloud, we packaged it into a managed RL fine-tuning service (RLFT service) — you bring prompts and a reward function; we handle the infrastructure and the proprietary model internals.
Now, you can adapt Gemini with the service — teaching the model from a reward signal you define, rather than from a fixed set of labeled answers. This unlocks a class of problems that supervised fine-tuning (SFT) struggles with: tasks that are hard to demonstrate but easy to score.
In this guide, we will walk through practical best practices for using RL fine-tuning service. We'll start with a short tour of the RL training loop, how to decide if and when to use RL, and introduce how to get the most value from this approach.
RLFT adapts Gemini from a reward signal you define rather than labeled answers. Instead of authoring a large set of gold examples, you write one program that scores a response and the service improves the model against it — unlocking tasks that are hard to demonstrate but easy to verify : you can't hand-write the ideal SQL for every schema, but you can run the query and check the result.
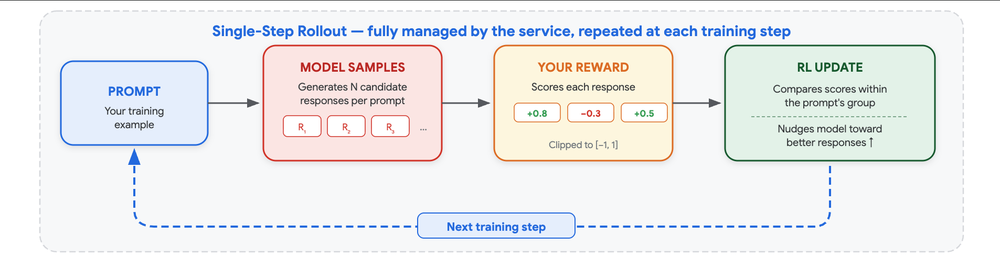
At each training step the service generates multiple candidate responses to your prompts, scores them with your reward, and improves the model so that higher-scoring responses become more likely while it stays close to the original Gemini. The reinforcement learning that makes this work is fully managed — you never configure it. The one thing you own, and the thing that most determines your results, is the reward.
Three properties define what RLFT can and can't do:
It learns from the model's own outputs: It refines what the model already produces rather than copying an external target, so it tends to disturb unrelated capabilities less than SFT.
It rewards outcomes, not paths: Any response that reaches a good result earns reward, which fits open-ended tasks with many valid solutions.
Cryptographic Security & Key Generator
Generate entropy-tested high-security keys and encryption-grade tokens.
Source: Cloud Blog.
Read the full story at the original source ↗
For questions: mrsmithcons@gmail.com.
Unlock Up to $10,000 in Free AWS, GCP & Azure Credits for Builders and Developers
The developer portal for modern cloud infrastructure: claim free cloud credits, discover generous free-tier developer tools, and optimize DevOps pipelines.
Claim Cloud Credits ➔☁️ Complete Cloud Credit Application Guide & Architecture Specs
Direct application templates, fast-track partner codes, and architecture benchmarks.
⚡ Access Cloud Playbook ➔More from FreeSky Cloud

 🤖 WinBar AI
Выбор ИИ для студенческого футбола на неделе 4: Техас-Теннесси и Орегон-USC
Главное освещение, о котором сообщает Sports Betting Dime: Неделя 4, выбор AI для студенческого футбола: Техас...
 🗺️ FreeSky GeoData
Solar Power Architecture & Off-Grid Battery Redundancy for 3D Photogrammetry
Comprehensive 2026 research dossier and telemetry report on Solar Power Architecture & Off-Grid Battery Redund...
 ⚡ CyberTech 568
Meta поддерживает Muse, когда приложение AI становится все более популярным
Muse возглавляет чарты магазинов приложений и стремительно набирает пользователей, в то время как Meta наращив...
Canine Athlete Exhibits Aerial Skills While Chasing Drone
A lively dog embarks on an exhilarating quest to capture a flying drone. With a fierce glimmer of determinatio...