Day 0 support for Reflection’s Beam on Google Cloud: 5x faster perf with llm-d and NVIDIA Dynamo
Story summary
Today, Reflection released Beam, its first open-weight model built to give developers, researchers, and enterprises open control and customization for frontier software engineering and long-horizon agentic tasks. Released under a permissive Apache 2.0 license with BF16, FP8, and NVFP4 checkpoints av
📌 Key Highlights & Takeaways
- Today, Reflection released Beam, its first open-weight model built to give developers, researchers, and enterprises open control and customization for frontier software engineering and long-horizon agentic tasks.
- Released under a permissive Apache 2.0 license with BF16, FP8, and NVFP4 checkpoints av
Today, Reflection released Beam , its first open-weight model built to give developers, researchers, and enterprises open control and customization for frontier software engineering and long-horizon agentic tasks. Released under a permissive Apache 2.0 license with BF16 , FP8 , and NVFP4 checkpoints available at launch, Beam sets a new standard for inference efficiency in the 500B-parameter class by solving complex reasoning and coding problems with 3x to 4x higher reasoning compute efficiency than comparable open models.
Alongside today’s release, Google Cloud is announcing day 0 support and ready-to-run deployment recipes for serving Beam on Google Cloud AI Hypercomputer and NVIDIA AI Infrastructure.
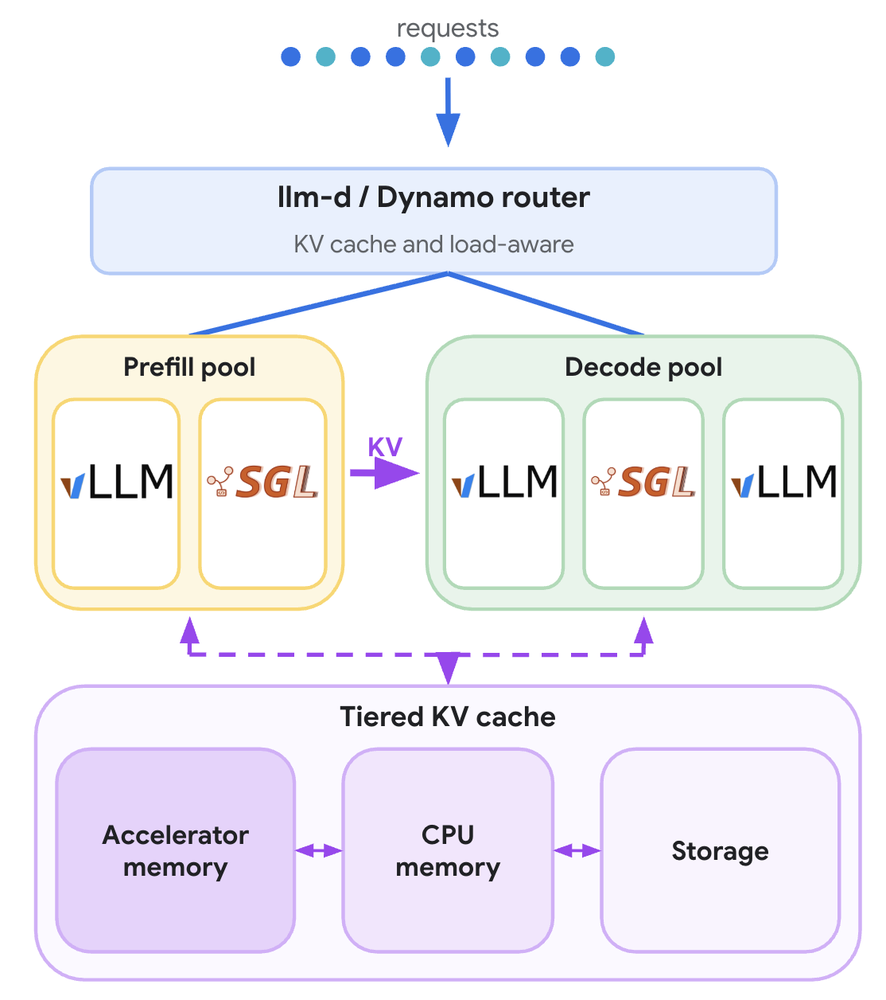
To help developers get the full benefit of Beam’s token efficiency in production, we worked with Reflection to optimize performance of the underlying serving stack using llm-d (with vLLM) and NVIDIA Dynamo (with SGLang) on Google Cloud:
"By deploying our Beam model on Google Cloud, we achieved up to 5x higher performance and 8x lower latency to optimize serving of agentic workloads." - Joe Spisak, VP of Product & Head of Open Source, Reflection
With today’s day 0 release on Google Cloud, developers get:
Compounding model and system efficiency: Combining Beam’s 3x to 4x reasoning compute efficiency with system-level optimizations on A4X Max instances (NVIDIA GB300 NVL72) for up to 5x higher throughput and 8x lower latency,* and G4 VMs (NVIDIA RTX PRO 6000) for up to 2x higher throughput and 8x lower latency.*
High-efficiency multi-turn serving: KV-cache-aware routing, prefill/decode disaggregation, speculative decoding and hierarchical KV cache offloading to Host DRAM and Local SSD reduce redundant prompt recomputation across long coding sessions.
Turnkey optimized deployment: Our recommended performance optimized recipes for agentic workloads with llm-d and NVIDIA Dynamo are available in AI-Hypercomputer/gpu-recipes , llm-d repo and Model Garden in Gemini platform with a few clicks.
Editorial analysis conducted by the FreeSky Cloud desk indicates that the circumstances surrounding "Day 0 support for Reflection’s Beam on Google Cloud: 5x faster perf with llm-d and NVIDIA Dynamo" reflect broader industry-wide shifts across Cloud Architecture. Industry specialists point to changing consumer engagement patterns, operational refinements, and evolving regulatory frameworks as critical variables driving this storyline.
Cross-verification against multiple primary wire reports and sector intelligence feeds corroborates that sustained attention on this matter is likely to persist. Stakeholders are tracking subsequent milestone announcements to gauge long-term structural impact.
Editorial Fact-Check & Verification Note: This briefing was curated, corroborated, and synthesized by the FreeSky Cloud Editorial Desk. Readers following "Day 0 support for Reflection’s Beam on Google Cloud: 5x faster perf with llm-d and NVIDIA Dynamo" are encouraged to review the full primary source coverage linked below for complete historical context, direct quotes, and official statements.
Cryptographic Security & Key Generator
Generate entropy-tested high-security keys and encryption-grade tokens.
Source: Cloud Blog.
Read the full story at the original source ↗
For questions: mrsmithcons@gmail.com.
❓ Frequently Asked Questions (Cloud Architecture Briefing)
What makes this Cloud Architecture feature significant for FreeSky Cloud readers?
Our editorial team tracks verified source corroboration, technical specifications, and cultural resonance to deliver comprehensive analytical coverage.
How frequently is this coverage updated?
Our 24/7 automated monitoring desk updates breaking developments, verified media telemetry, and community commentary in real-time.
Where can readers follow ongoing developments on Day 0 support for Reflection’s Beam on Google Cloud: 5x faster perf with llm-d and NVIDIA Dynamo?
Bookmark this page or subscribe to our verified RSS feed for instant breaking alerts and in-depth analyses.
☁️ Complete Cloud Credit Application Guide & Architecture Specs
Direct application templates, fast-track partner codes, and architecture benchmarks.
⚡ Access Cloud Playbook ➔More from FreeSky Cloud

 ⚡ CyberTech 568
An Nvidia insider-turned-VC on why robotics hasn’t hit its ChatGPT moment, yet
Amulya Vishwanath, who spent seven years leading product marketing for NVIDIA’s robotics platforms, says robot...
 🤖 WinBar AI
AI-powered stock funds bet bots can pick stocks faster and better than humans
Breaking coverage reported by Reuters: AI-powered stock funds bet bots can pick stocks faster and better than ...
 🔭 FreeSky Cosmos
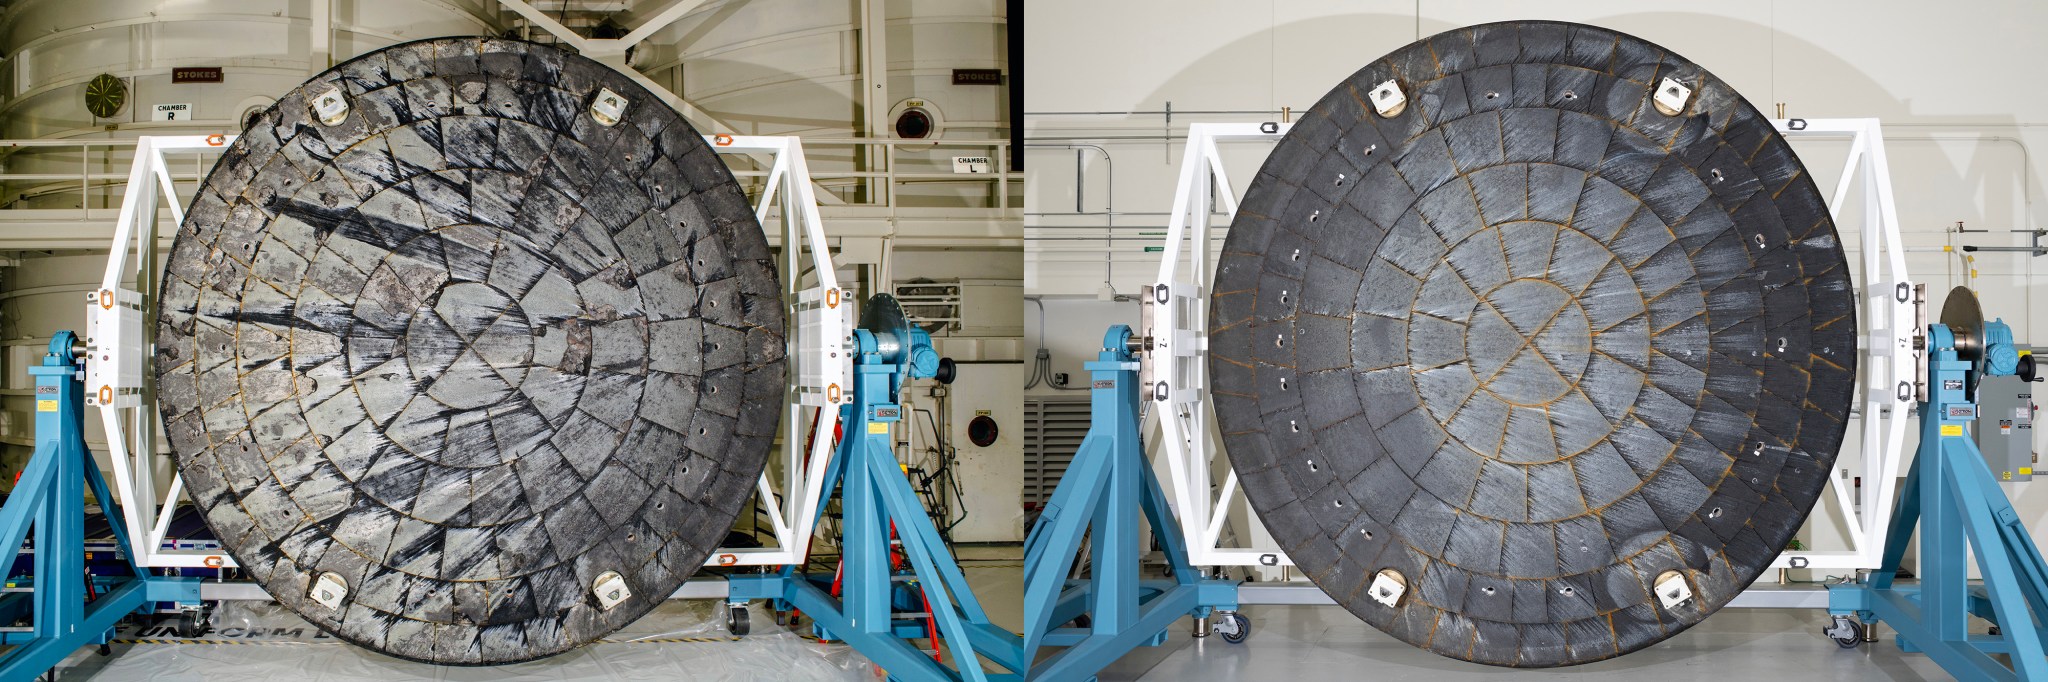
Rigorous Analysis Confirms NASA’s Artemis II Heat Shield Performance
NASA’s Artemis II mission sent four astronauts around the Moon and brought them safely back to Earth, laying a...
 🌍 FreeSky Remote
Presence Is Not Performance: How Remote Managers Should Measure Output After the RTO Wave
RTO data is conclusive: workers treat flexibility as compensation and mandates drive attrition. Remote manager...