Guía de mejores prácticas para personalizar modelos Gemini mediante aprendizaje por refuerzo (RL)
Story summary
El aprendizaje por refuerzo (RL) ha sido una piedra angular de la posformación de LLM moderna, pero exige grandes grupos de formación y acceso a modelos internos que los clientes externos no pueden tener con modelos propietarios como Gemini. Por eso, aquí en Google Cloud, lo empaquetamos en un servicio de ajuste fino de RL administrado (RLF
📌 Key Highlights & Takeaways
- El aprendizaje por refuerzo (RL) ha sido una piedra angular de la posformación de LLM moderna, pero exige grandes grupos de formación y acceso a modelos internos que los clientes externos no pueden tener con modelos propietarios como Gemini.
- Por eso, aquí en Google Cloud, lo empaquetamos en un servicio de ajuste fino de RL administrado (RLF
Reinforcement learning (RL) has been a keystone of modern LLM post-training, but it demands large training clusters and access to model internals that external customers can't have with proprietary models like Gemini. So here at Google Cloud, we packaged it into a managed RL fine-tuning service (RLFT service) — you bring prompts and a reward function; we handle the infrastructure and the proprietary model internals.
Now, you can adapt Gemini with the service — teaching the model from a reward signal you define, rather than from a fixed set of labeled answers. This unlocks a class of problems that supervised fine-tuning (SFT) struggles with: tasks that are hard to demonstrate but easy to score.
In this guide, we will walk through practical best practices for using RL fine-tuning service. We'll start with a short tour of the RL training loop, how to decide if and when to use RL, and introduce how to get the most value from this approach.
RLFT adapts Gemini from a reward signal you define rather than labeled answers. Instead of authoring a large set of gold examples, you write one program that scores a response and the service improves the model against it — unlocking tasks that are hard to demonstrate but easy to verify : you can't hand-write the ideal SQL for every schema, but you can run the query and check the result.
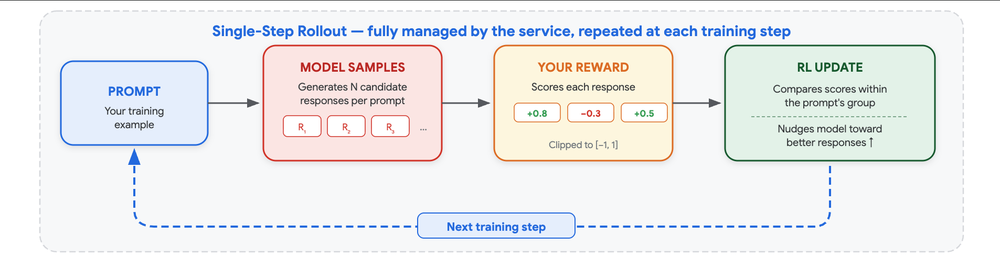
At each training step the service generates multiple candidate responses to your prompts, scores them with your reward, and improves the model so that higher-scoring responses become more likely while it stays close to the original Gemini. The reinforcement learning that makes this work is fully managed — you never configure it. The one thing you own, and the thing that most determines your results, is the reward.
Three properties define what RLFT can and can't do:
It learns from the model's own outputs: It refines what the model already produces rather than copying an external target, so it tends to disturb unrelated capabilities less than SFT.
It rewards outcomes, not paths: Any response that reaches a good result earns reward, which fits open-ended tasks with many valid solutions.
Cryptographic Security & Key Generator
Generate entropy-tested high-security keys and encryption-grade tokens.
Source: Cloud Blog.
Read the full story at the original source ↗
For questions: mrsmithcons@gmail.com.
More from FreeSky Cloud