Demokratisierung von Managed Lustre mit geringeren Kosten und reibungsloser Entwicklung

Story summary
Dies ist der erste Teil einer zweiteiligen Reihe, in der untersucht wird, wie Google Cloud die Grundwerte eines leistungsstarken parallelen Dateisystems – TB/s-Durchsatz, Sub-Ms-Latenz bei hoher Client-Skala und POSIX-Unterstützung – einem breiteren Spektrum von Anwendungsfällen und Benutzern zugänglich macht. Historisch gesehen, aufgrund der Kosten und besonderen p
📌 Key Highlights & Takeaways
- Dies ist der erste Teil einer zweiteiligen Reihe, in der untersucht wird, wie Google Cloud die Grundwerte eines leistungsstarken parallelen Dateisystems – TB/s-Durchsatz, Sub-Ms-Latenz bei hoher Client-Skala und POSIX-Unterstützung – einem breiteren Spektrum von Anwendungsfällen und Benutzern zugänglich macht.
- Historisch gesehen, aufgrund der Kosten und besonderen p
This is the first of a two-part series exploring how Google Cloud is bringing the foundational values of a high-performance parallel filesystem–TB/s throughput, sub-ms latency at high client scale, and POSIX support–to a broader set of use cases and users.
Historically, due to the cost and special purpose nature of parallel filesystems, colder data had to be stored outside of the filesystem and AI developers have had to maintain separate, slower environments for writing code, compiling libraries, and managing repositories. This fragmentation increases the toil of manual data staging, dataset copying, and managing disjointed namespaces.
Google Cloud Managed Lustre is solving these problems through our 6 cents/GB*month Dynamic Tier and by optimizing Managed Lustre performance for a range of development tasks and workloads – making Managed Lustre a “One-Stop Shop” for high-performance AI and HPC workloads.
The Managed Lustre Dynamic Tier provides sub-ms latency for hot data, which allows you to store all of your data in a single namespace, and costs only 6 cents/GB*month .
Throughput, capacity scale and client scale: Throughput scales linearly with capacity up to 80 PB, while sub-ms latency for hot data remains stable as you scale to tens of thousands of clients.
Single-flat fee: Predictable pricing. No independent charges for disk media types, data movement within the namespace, or metadata IOPS.
Read Latencies: Sub-ms latencies for High-Performance Cache (SSD). The Capacity Pool (“HDD”) is built on Google Cloud Hyperdisk throughput, which has an average read latency of 10 to 30 ms .
Multi-Epoch Training and/or Training with Optimized Fetch Sizes: Hot data is promoted to the High Performance Cache (SSD) after the first run. Larger data prefetch will allow you to take advantage of the Dynamic Tier cost structure and gain from low-latency SSD.
Cryptographic Security & Key Generator
Generate entropy-tested high-security keys and encryption-grade tokens.
Source: Cloud Blog.
Read the full story at the original source ↗
For questions: mrsmithcons@gmail.com.
☁️ Complete Cloud Credit Application Guide & Architecture Specs
Direct application templates, fast-track partner codes, and architecture benchmarks.
⚡ Access Cloud Playbook ➔More from FreeSky Cloud
Gimmick or recipe for success? Japan's convenience stores test AI flavours
Gimmick or recipe for success? Japan's convenience stores test AI flavours Japanese convenience store chains a...
 🤖 WinBar AI
Verliererspieler werden durch die KI von DraftKings dazu gedrängt, mehr zu wetten, heißt es in einem Bericht
Von Malwarebytes gemeldete aktuelle Berichterstattung: Verlierer werden durch die KI von DraftKings dazu gedrä...
Tallinn Defence EXPO: Counter-drone systems and robot soldiers steal the show
Tallinn Defence EXPO: Counter-drone systems and robot soldiers steal the show Drones have changed the face of ...
 🔭 FreeSky Cosmos
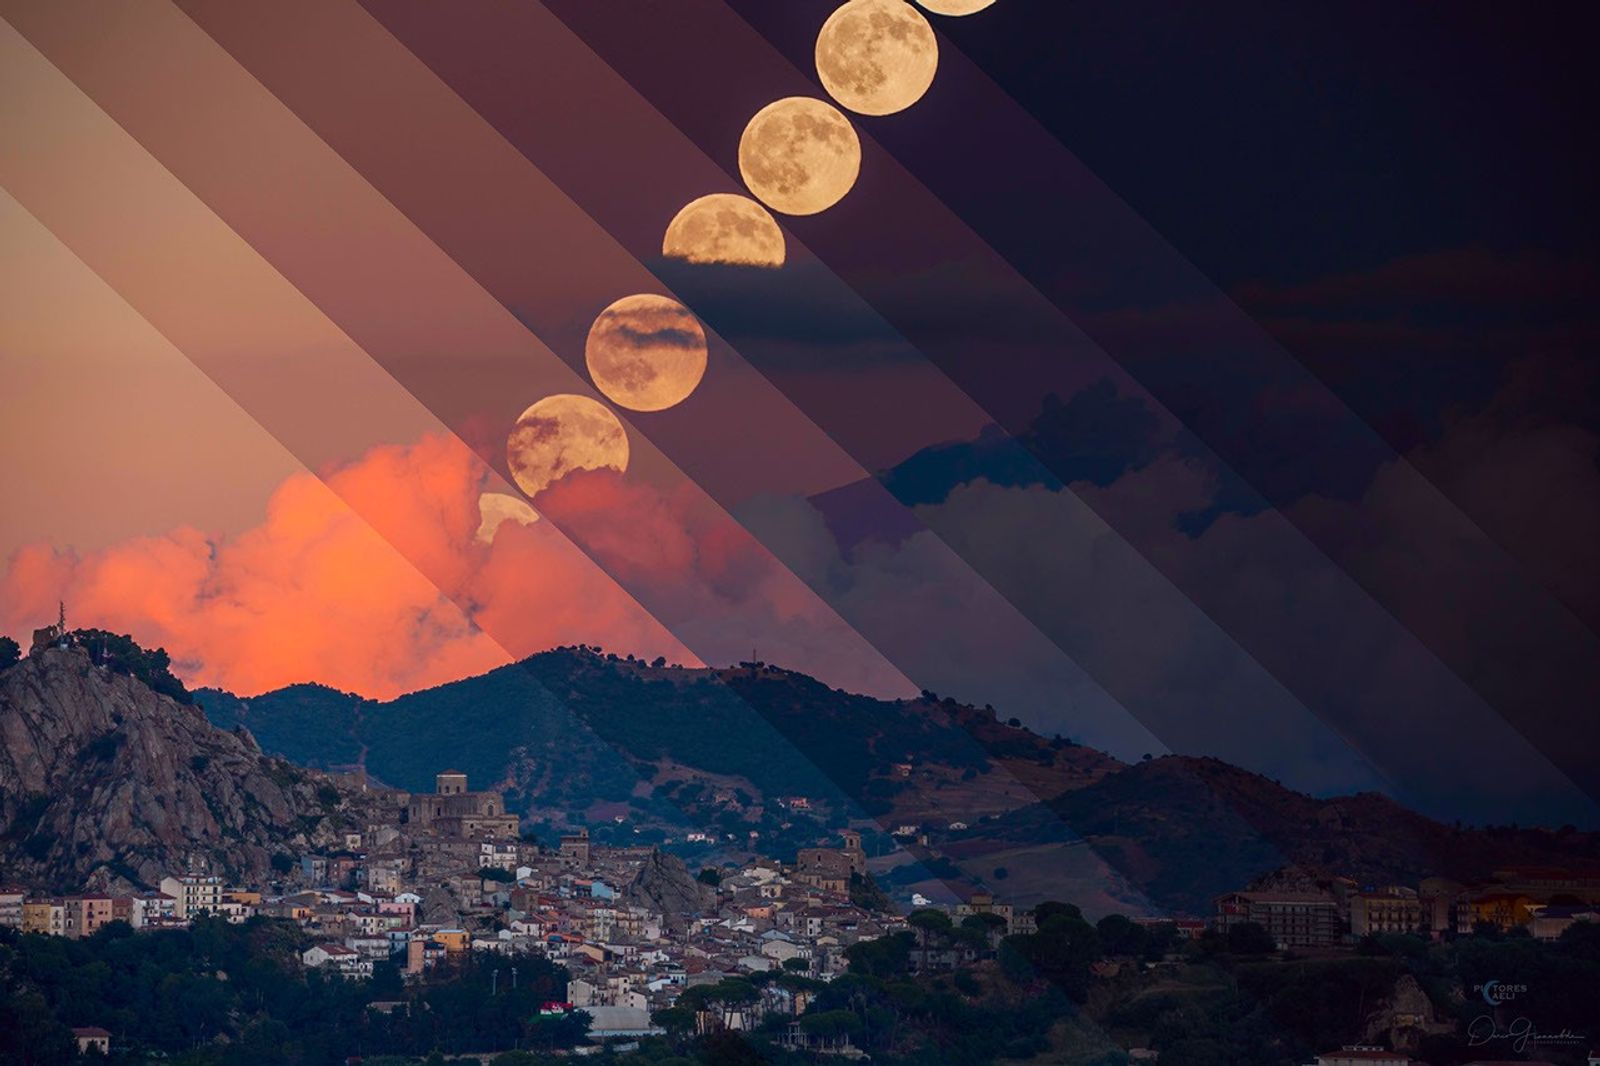
APOD: 2026 October 1 – Harvest Moon with Erupting Mount Etna
APOD Science APOD APOD: 2026 October 1 –… Today’s APOD Archive Submissions Index Search Calendar RSS Education...