AI21 erreicht mit AI Hypercomputer eine Reduzierung der Startzeit für KI-Workloads um 83 %
Story summary
Anmerkung des Herausgebers: AI21 Labs ist ein führendes globales KI-Labor mit einer langen Erfolgsgeschichte in der Entwicklung von Basismodellen, insbesondere der Jamba-Familie, und konzentriert sich heute auf spezialisierte LLMs und Agentenoptimierungstechnologie. Durch die Einführung des Google Cloud AI Hypercomputers konnte AI21 die Wartezeit für Aufträge mit hoher Priorität von 72 verkürzen
📌 Key Highlights & Takeaways
- Anmerkung des Herausgebers: AI21 Labs ist ein führendes globales KI-Labor mit einer langen Erfolgsgeschichte in der Entwicklung von Basismodellen, insbesondere der Jamba-Familie, und konzentriert sich heute auf spezialisierte LLMs und Agentenoptimierungstechnologie.
- Durch die Einführung des Google Cloud AI Hypercomputers konnte AI21 die Wartezeit für Aufträge mit hoher Priorität von 72 verkürzen
Editor’s note : AI21 Labs is a leading global AI lab with a long track record of building foundation models, most notably the Jamba family, and today focuses on specialized LLMs and agent optimization technology. By adopting Google Cloud AI Hypercomputer, AI21 cut high-priority job wait times from 72 hours to 12 and manual scheduling interventions from 20 per week to zero.
At AI21 , we build foundation models and agent optimization products that help enterprises run agents at frontier quality, efficiently. Our language models, including the Jamba family, and our agent optimization product suite run demanding production workloads, including our own. We chose Google Cloud AI Hypercomputer to support them at scale.
To keep our model training runs highly utilized, we needed a performant, scalable environment codesigned across infrastructure, orchestration, and consumption models. Our model training runs on one of our shared Google Kubernetes Engine (GKE) clusters, pooling thousands of Google Cloud A3 (powered by NVIDIA H100 Tensor Core GPUs) and A3 Ultra (powered by NVIDIA H200 Tensor Core GPUs) instances, so any team can draw on the full capacity of the fleet rather than being boxed into its own slice. The cluster also trains models and agent-optimization workloads beyond the Jamba family. That approach keeps utilization high, and it makes scheduling hard.
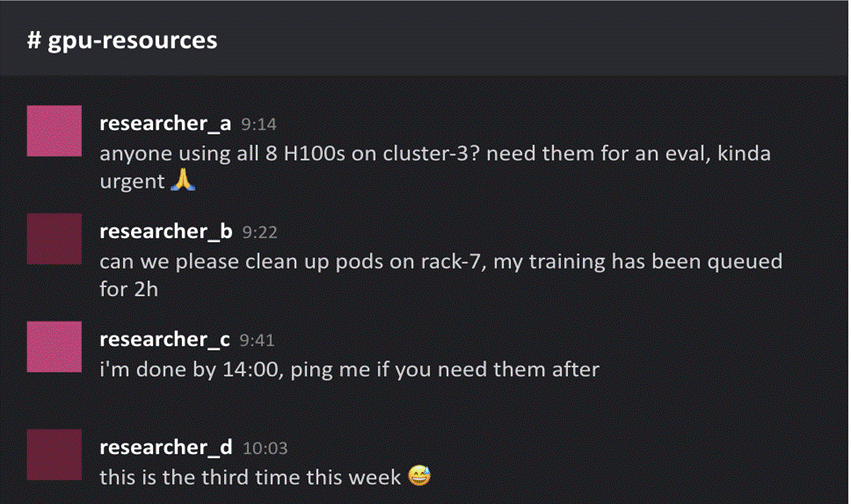
Prior to leveraging GKE for orchestration, we used to negotiate capacity by hand in Slack. If you needed capacity for a training run, you posted in #gpu-resources and hoped for the best.
That worked fine when the cluster had headroom. It stopped working once utilization pinned near 100%, which is where you want a reserved compute fleet to sit.
Over time, every request became a negotiation. Team leads spent their time refereeing compute disputes. Our high-priority jobs — the large, multi-node training runs that need half or more of the cluster at once and serve as the critical path for model projects — could sit blocked for up to 72 hours waiting for enough contiguous capacity to open up.
Scarcity created two distinct problems, and it took us a while to see them as separate. The first was contention: determining who gets compute access next, which we resolved through negotiation. The second was fragmentation: capacity that was technically free but scattered in pieces too small for a large job to use, a bin-packing problem no amount of negotiation could fix.
Sometimes we had plenty of capacity free on paper, but it was scattered across different machines in chunks too small for a larger job to actually land. Without all-or-nothing admission, the cluster could reach a deadlock, with machines holding resources without doing useful work until someone stepped in manually.
Cryptographic Security & Key Generator
Generate entropy-tested high-security keys and encryption-grade tokens.
Source: Cloud Blog.
Read the full story at the original source ↗
For questions: mrsmithcons@gmail.com.
☁️ Complete Cloud Credit Application Guide & Architecture Specs
Direct application templates, fast-track partner codes, and architecture benchmarks.
⚡ Access Cloud Playbook ➔More from FreeSky Cloud

Get rules in place to hold data centres to account, experts tell Tasmania, ahead of AI entrenching itself
Artificial intelligence experts are urging Tasmania to introduce binding rules to ensure data centre developme...
 🤖 WinBar AI
New York steht vor einem Steuereinnahmenrisiko, da Prognosemärkte das Sportwettenmodell in Frage stellen
Aktuelle Berichterstattung von Traders Union: New York steht vor Steuereinnahmenrisiko, da Prognosemärkte das ...
SHOCKING FOOTAGE: Iran SEIZES Second U.S. Drone In Hormuz, Threatens Reverse-Engineering Nightmare
Iran’s Islamic Revolutionary Guard Corps (IRGC) says it has seized a U.S. REMUS 600 autonomous underwater vehi...
Watch SpaceX Starship Lift Off In Amazing Slow Motion Footage From Flame Trench
SpaceX's flight 9 Starship launched from Starbase in Texas. See views from below and more in this slow motion ...